DeepInfer vs vLLM, SGLang & TensorRT-LLM
Heritage, when to choose which stack, feature checklist, and what OSS does not include. Prefill is not a separate product.
Heritage
From the official Acknowledgments: DeepInfer was originally built primarily on vLLM, with additional inspiration from SGLang and TensorRT-LLM. That is lineage — not a claim that every vLLM feature is present.
When to choose DeepInfer vs vLLM
| Option | Best when | Offline V4.1-Flash path? | Hardware gate |
|---|---|---|---|
| DeepInfer | You want DeepSeek’s open engine for V4.1-Flash offline on listed accelerators | Yes (primary) | SM100 / Ascend 950 |
| vLLM / SGLang | Broader model zoo, other GPUs, or you already standardize on that stack | Depends on their support | Their matrix |
| TensorRT-LLM | NVIDIA-centric TRT pipelines | Different product | NVIDIA / TRT |
| Official API | Hosted inference; no GPU ops | Hosted | N/A |
Feature checklist (DeepInfer OSS)
| Capability | In DeepInfer OSS? | Source note |
|---|---|---|
| Offline DeepSeek-V4.1-Flash | Yes | README supported model |
| Optimized kernels (FlashMLA, DeepGEMM, DeepEP, …) | Yes | README feature details |
| Attention DP / balanced CP · MoE EP + EPLB | Yes | README |
| DSpark + confidence-scheduled verification | Yes | Env flags in README |
| SWA bounded replay · async scheduling · structured outputs | Yes | README |
| Batch-invariant / deterministic sampling (NVIDIA) | Yes | README |
| Full KV cache system | No | Listed as required, not included |
| Complete VE/Prefill/Decode disagg serving | No | Engine parts exist; service glue not released |
| DP load balancing for P/D replicas | No | Listed as required, not included |
What OSS does NOT include
- A turnkey multi-tenant online API with long-retention KV
- Production Prefill/Decode disaggregation service (phases exist in one engine; full glue is out of tree)
- DP load balancers for prefill and decode replicas
- Agent runtime — that is DeepSeek Harness · dshbase.com
- Protocol conversion alone — that is deepseek-recipe (does not infer)
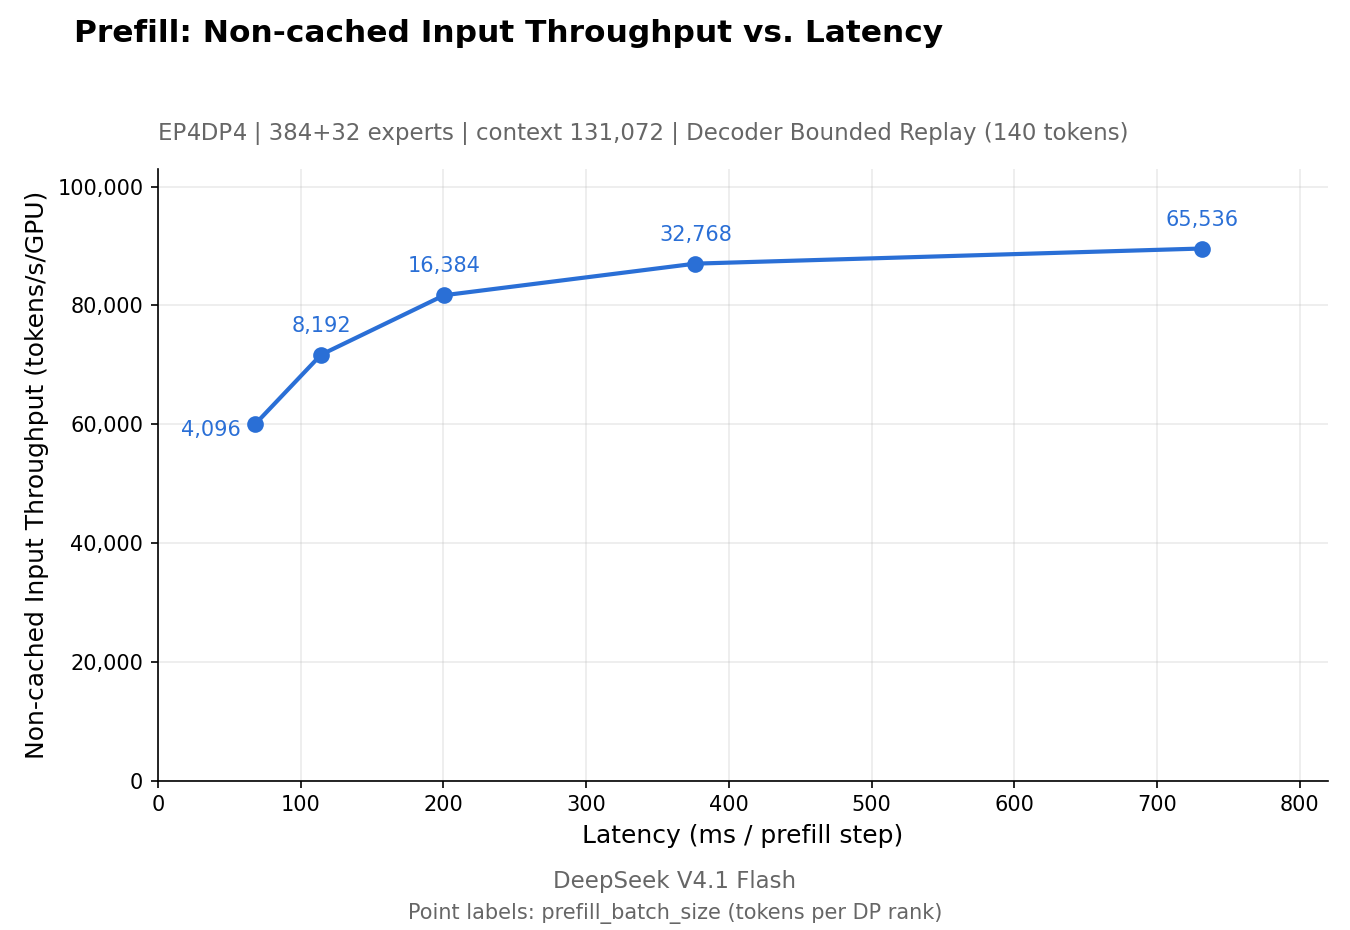
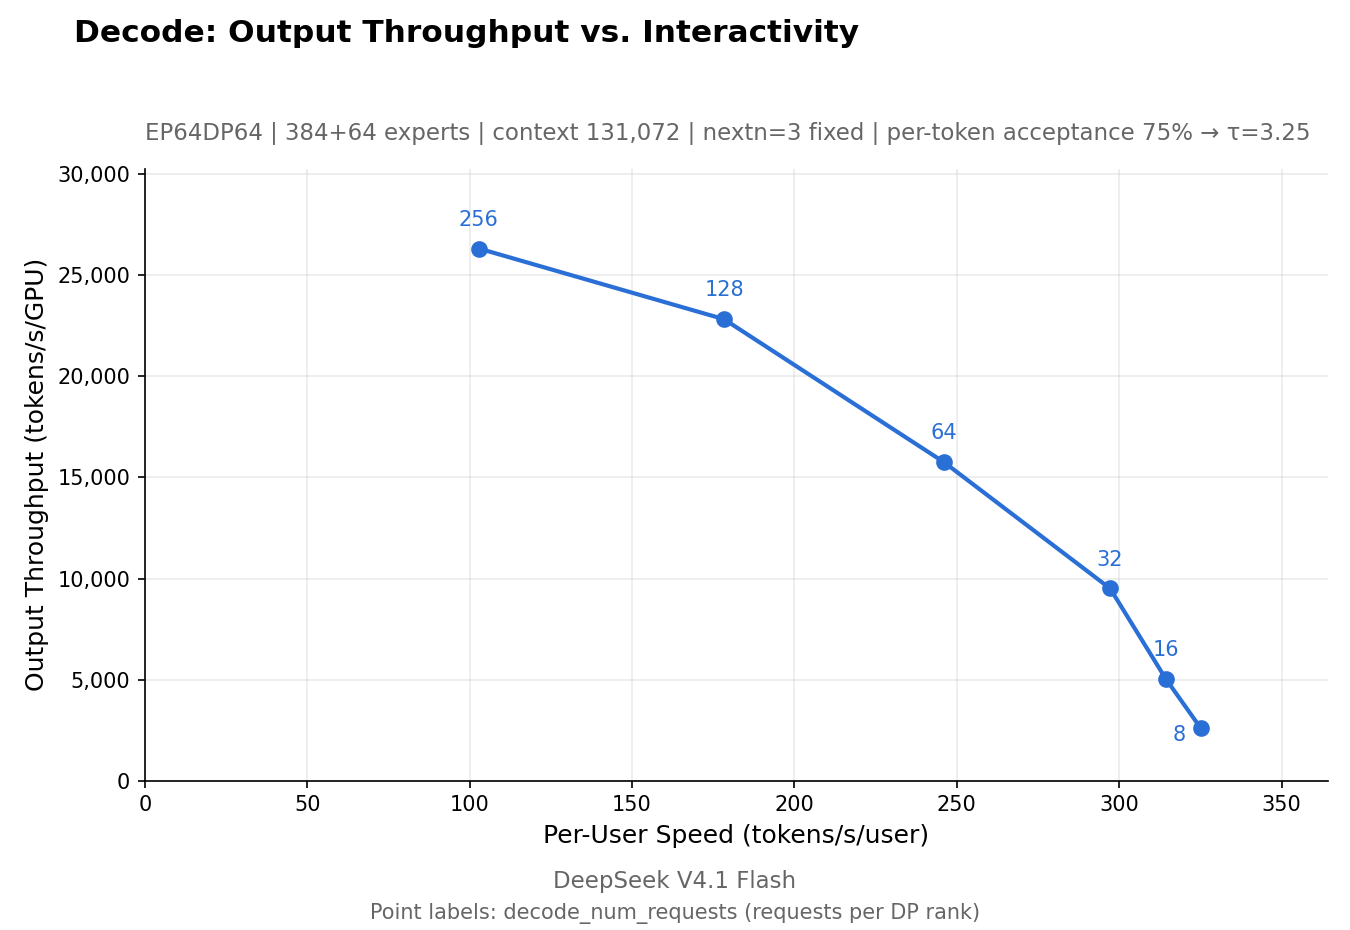
Prefill ≠ separate product. Prefill and Decode are two phases of the same DeepInfer engine. Charts that show 4× SM100 (prefill) vs 64× SM100 (decode) are topology for benchmarks — not two installs. See Prefill vs Decode.
Capability comparison (guide synthesis)
Community write-ups (e.g. WeChat capability roundups) often compare stacks along these axes. Treat as a guide checklist, not a vendor scorecard — always verify against live READMEs.
| Axis | DeepInfer OSS | vLLM | SGLang |
|---|---|---|---|
| Primary focus | DeepSeek V4.1-Flash offline engine | Broad model zoo / general serving | Fast serving + structured workflows |
| Heritage | Built primarily on vLLM; inspired by SGLang & TRT-LLM | Original project | Independent stack |
| Listed HW (DeepInfer README) | SM100 + Ascend 950 | Wide NVIDIA (+ others via backends) | Wide NVIDIA focus |
| Offline kernels / EP-DP | Yes (FlashMLA-family, EP/DP/CP) | Yes (own kernels) | Yes |
| Full KV + PD service + DP LB | Not in OSS | Serving features vary by version | Serving features vary |
| Official Docker (DeepInfer) | None — community Dockerfile = example only | Project images common | Project images common |
Official Prefill / Decode charts
From DeepInfer doc/images/ (Apache-2.0). Measured on 4× SM100 (prefill) and 64× SM100 (decode) — same engine, two phases.